On this page · 4 sections
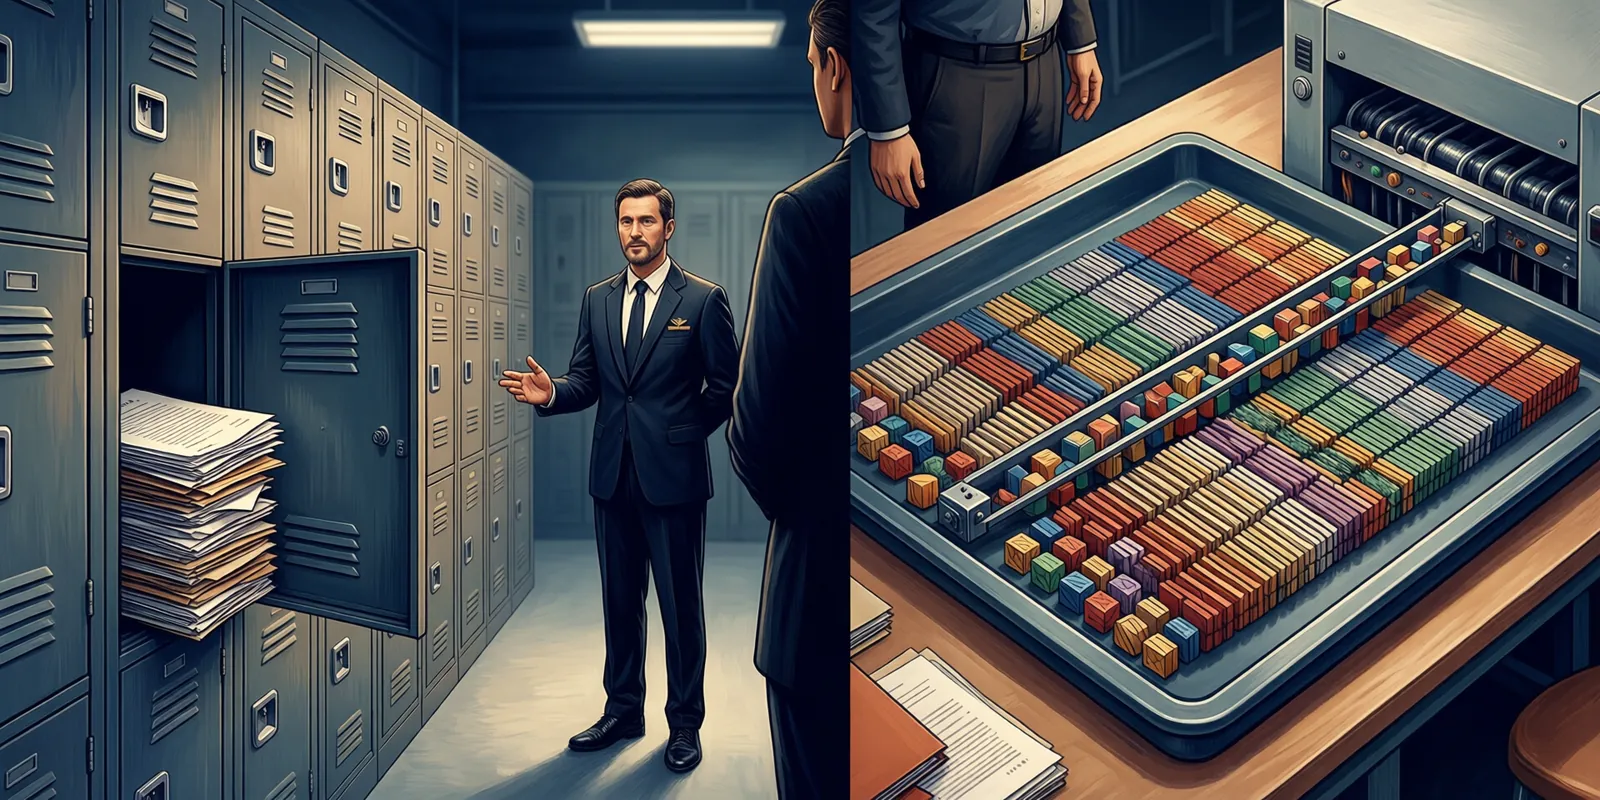
Two llama.cpp builds from October 10 and 11, 2026 change very different parts of the project. llama.cpp b11552 fixes a server bug in which one request could switch another request's context, and llama.cpp b11554, published about 17 hours later from the same branch, changes how the Vulkan backend dispatches mixture-of-experts matrix multiplications. They are consecutive points on master, not alternatives: b11554 already includes the b11552 fix.
| Criterion | b11552: server slots | b11554: Vulkan MoE |
|---|---|---|
| Area | HTTP server slot handling (#30295) | Vulkan mul_mat_id and mul_mm_id (#29998) |
| Problem | A request pinned to a busy slot ran the prompt cache update on it before being deferred | Duplicate expert IDs were handled by looping |
| Change | The busy slot is returned as is and the request waits | Duplicates are handled in a prepass that emits a compact list of tiles |
| Effect | Generation no longer continues on the wrong context | A tighter upper bound on workgroups, with an early exit for the tail |
| Who should care | Servers with prompt caching and requests that pin id_slot | MoE models on the Vulkan backend |
b11552: A Busy Slot Could Receive Another Request's Context #
The llama.cpp b11552 notes describe the bug: a request asking for a busy id_slot still ran the prompt cache update on that slot before being deferred. When the RAM cache held a better match, it was loaded into the slot while another request was still generating there, "and that generation continued on the wrong context." Since b11552 the busy slot is returned as is and the request waits for it.
For a server shared by several users, that means one user's request could change the context another user's generation was running on. The fix needs no configuration; any build from b11552 onwards contains it.
b11554: Vulkan MoE Duplicates Move Into the Prepass #
In llama.cpp b11554, the Vulkan backend computes every row of an expert in mul_mm_id when IDs repeat and handles mul_mat_id duplicates in the prepass rather than by looping. The "hoist row ids" optimization is now always enabled and emits a compact list of tile descriptions that need to run, with multiple tiles when needed, so the backend can launch a tighter upper bound on the number of workgroups and the tail can trivially early exit. The notes give no benchmark figures and do not name specific GPUs.
Which Build to Run #
- Servers that use prompt caching and pin requests to slots should run b11552 or any later build.
- Vulkan users running MoE models get the dispatch change from b11554 onwards.
- Since b11554 contains both changes, there is no reason to stop at b11552; a current build includes both.
The Sentinel’s Call
The server fix in b11552 is the one with real consequences, because a pinned request could make another user's generation continue on the wrong context. The Vulkan change in b11554 is an internal dispatch improvement. Both are in every later build, so updating to a current build covers them.
Our judgement, drawn only from the facts and sources above.
Sources
- Release b11554 · ggml-org/llama.cpp · GitHub github.com · Oct 11, 2026
- Release b11552 · ggml-org/llama.cpp · GitHub github.com · Oct 10, 2026
More on llama.cpp
3 other articles, newest first
- NewerOct 28, 2026llama.cpp v0.8.0 and b11972: CLI Now Requires --model or -hf
- NewerOct 25, 2026llama.cpp b11871 and b11873: JSON Depth Limit and Q2_K on Adreno
- NewerOct 19, 2026llama.cpp b11724: Faster Hexagon Flash Attention, CUDA Race Fix
Next reading
Edited and approved by Jarosław Krzemiński. Spotted a mistake? Report a correction or read the corrections policy.
Comments